

File size: 7,872 Bytes
f3be80e c825458 f3be80e c825458 | 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 102 103 104 105 106 107 108 109 110 111 112 113 114 115 116 117 118 119 120 121 122 123 124 125 126 127 128 129 130 131 132 133 134 135 136 137 138 139 140 141 142 143 144 | ---
license: apache-2.0
library_name: pytorch
pipeline_tag: image-segmentation
base_model: facebook/sam2-hiera-small
base_model_relation: adapter
tags:
- personalized-segmentation
- personalized-retrieval
- image-retrieval
- segment-anything
- arxiv:2608.29917
---
# FoundYou: A Unified Model for Personalized Segmentation and Retrieval
[Paper](https://huggingface.co/papers/2608.29917) ([arXiv](https://arxiv.org/abs/2608.29917)) · [Code](https://github.com/ga1i13o/FoundYou) · [Project page](https://ga1i13o.github.io/FoundYou/) · [Demo](https://gmberton.github.io/demos-url/foundyou/)
**ECCV 2026** · Gabriele Trivigno\*, Marcos Alfaro\*, Claudia Cuttano\*, Gabriele Berton, Luis Payá, Carlo Masone (\* equal contribution)
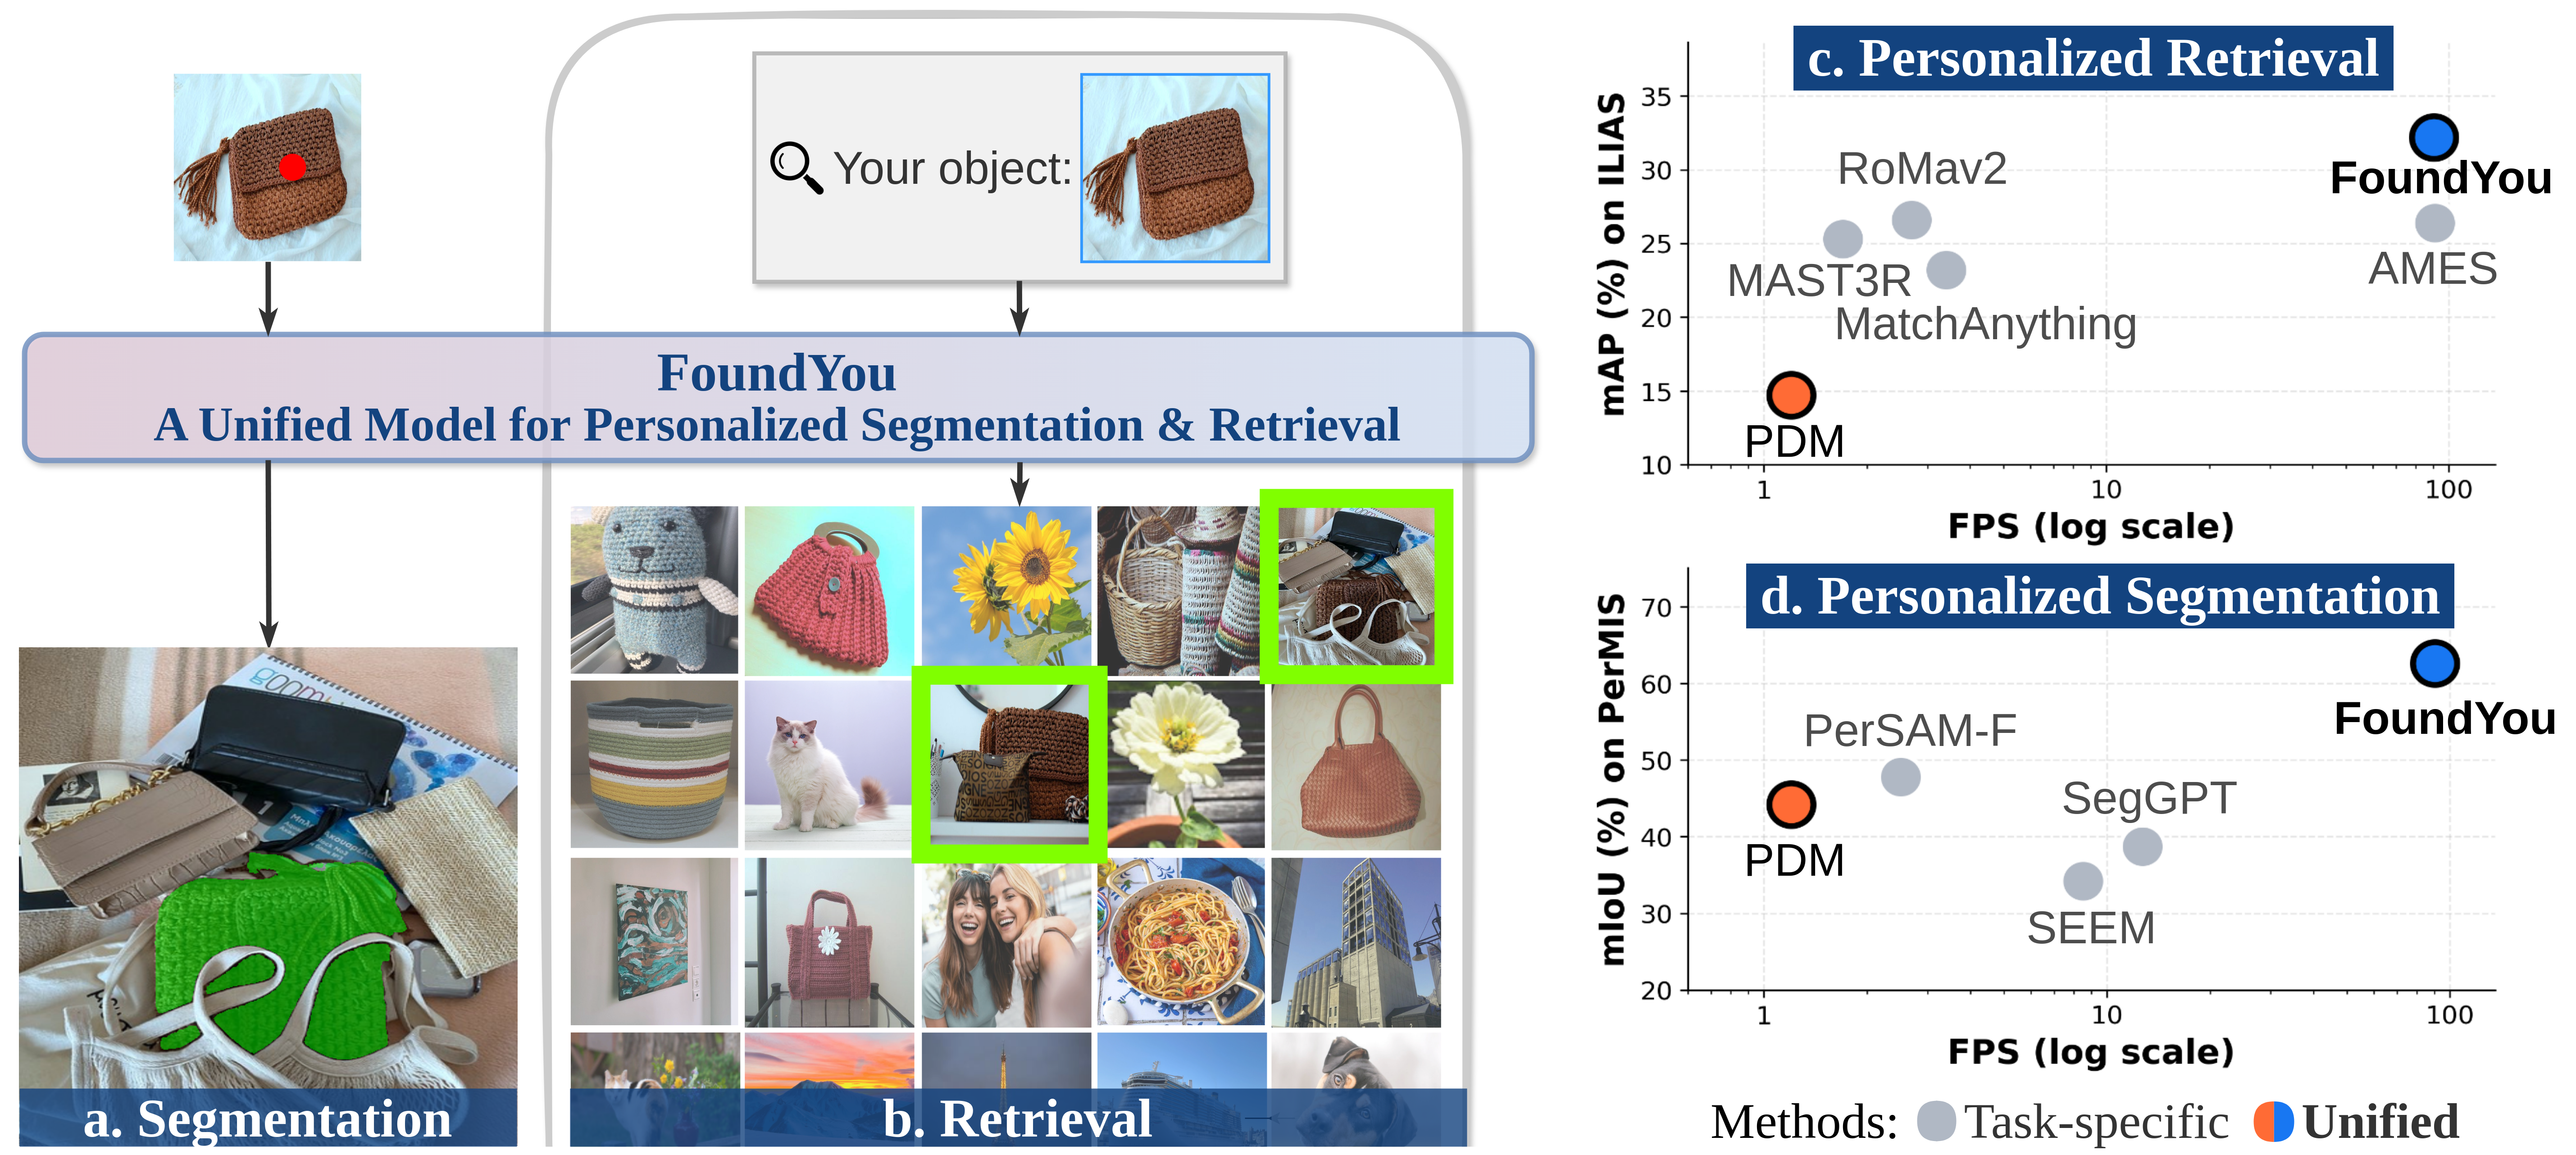
Give FoundYou one example of your object: segment it in new images or retrieve it from a large database with a single efficient model. FoundYou keeps SAM 2-small frozen and uses its memory attention to match an object across independent images instead of across video frames. It adds lightweight adapters to the image encoder and a retrieval decoder that turns the match into an image-level score, while the frozen SAM 2 mask decoder produces the masks.
- **Flexible personalization:** use mask, box, or point prompts for segmentation and multiple references for few-shot retrieval
- **State-of-the-art performance:** improves over the prior unified method by +18.4 mIoU on PerMIS and +17.8 mAP on ILIAS
- **Compact and fast:** a 52 M-parameter model with only 5.9 M trainable parameters, over 75× faster and 20× smaller than the prior unified solution
## Files
- `model.safetensors`: the 5.9 M trained parameters, i.e. the AdaptFormer adapters in the last two stages of the SAM 2 image encoder and the trained parts of the retrieval decoder (its transformer and object-score head). They were trained on UnED (Ypsilantis et al., ICCV 2023), with SAM 2 frozen.
- `config.json`: the model settings (the same values as `configs/*.yaml` in the code).
The frozen SAM 2-small weights are not in this repository: the code downloads them to `pretrain/` the first time the model is built (the same `sam2_hiera_small.pt` file as in [facebook/sam2-hiera-small](https://huggingface.co/facebook/sam2-hiera-small)).
## Usage
```bash
git clone https://github.com/ga1i13o/FoundYou && cd FoundYou
conda create --name foundyou python=3.10 -y && conda activate foundyou
pip install -r requirements.txt huggingface_hub safetensors
```
Save the example below as `example.py` in the repository root and run `python example.py` there (or paste it into Python started in the repository root). It uses the images in `assets/`: a reference photo of a toy with a box around it, 10 other photos of the same toy, and the paper's teaser figure, which does not show the toy.
```python
import os
import torch
from huggingface_hub import snapshot_download
from PIL import Image
from safetensors.torch import load_file
from torchvision import transforms
from datasets.transform_utils import load_box
from models.foundyou import build_foundyou
from util.promptable_utils import build_prompt_dict
device = "cuda" if torch.cuda.is_available() else "cpu"
weights = load_file(os.path.join(snapshot_download("gabTriv/FoundYou"), "model.safetensors"))
def load_model(config_path):
model = build_foundyou(config_path) # the first call downloads SAM 2-small to pretrain/
model.load_state_dict(weights, strict=False) # the file has only the trained parameters
return model.to(device).eval()
# Same weights, with the settings that the evaluation scripts use for each task
retrieval_model = load_model("configs/retrieval.yaml")
segmentation_model = load_model("configs/pers_seg.yaml")
# Same preprocessing as the evaluation scripts (the model resizes to 1024x1024 internally)
transform = transforms.Compose([
transforms.Resize((518, 518)),
transforms.ToTensor(),
transforms.Normalize([0.485, 0.456, 0.406], [0.229, 0.224, 0.225]),
])
def load_image(path):
return transform(Image.open(path).convert("RGB")).to(device)
# Reference: a photo of the object and a box around it, as [x1, y1, x2, y2] in the 518x518 frame
folder = "assets/spry_toodlesnap_863"
width, height = Image.open(f"{folder}/query/Q863_00.jpg").size
box_file = f"{folder}/query/Q863_00_bbox.txt" # "x y w h" in pixels
box = load_box(box_file, original_size=(height, width), transformed_size=(518, 518))
reference = load_image(f"{folder}/query/Q863_00.jpg")
prompt = build_prompt_dict(box, "box", device)
photos = [f"{folder}/positives/P863_{i:02d}.jpg" for i in range(10)]
not_the_toy = "assets/FoundYou_teaser.png" # the paper's teaser figure, without the toy
with torch.no_grad():
# Personalized retrieval: the probability that each photo shows the reference object
context = retrieval_model.encode_references([reference], [prompt])
for path in photos + [not_the_toy]:
logit = retrieval_model.score_candidates(load_image(path)[None], context) # batch of 1
print(f"{path}: {logit.sigmoid().item():.2f}")
# Personalized segmentation: the mask of the object in a new photo
context = segmentation_model.encode_references([reference], [prompt])
logits = segmentation_model.segment_candidates(load_image(photos[0])[None], context)
mask = logits.sigmoid() > 0.5 # [1, 518, 518]
print(f"The mask covers {mask.float().mean().item():.0%} of {photos[0]}")
```
It prints a score between 0 and 1 for each image (higher means more likely to show the reference object): from 0.5 to 1.0 for the 10 photos of the toy, and about 0.05 for the teaser figure, which does not show it. Then it prints the share of the first photo covered by the predicted mask.
- The mask is in the 518x518 frame: resize it to the photo size to overlay it. For your own photos, make the box with `box = torch.tensor([x1, y1, x2, y2])` in the same frame (x times 518 / width, y times 518 / height) and pass it to `build_prompt_dict(box, "box", device)`.
- To use several reference photos of the same object, pass them all to `encode_references`, with one prompt each.
- For a point prompt, pass `{"prompt_type": "point", "prompt": {"point_coords": torch.tensor([[[x, y]]], dtype=torch.float32, device=device), "point_labels": torch.tensor([[1]], dtype=torch.int32, device=device)}}` instead of `prompt`, with (x, y) in the 518x518 frame. For mask prompts, see `inference_pers_seg.py`.
- For evaluation on PerSeg, PerMIS, PerMIR and ILIAS, see the [GitHub README](https://github.com/ga1i13o/FoundYou).
## Results
Results from the paper (segmentation with mask prompts; ILIAS: re-ranking the top 1,000 images retrieved by SigLIP, which alone reaches 19.6 mAP). FoundYou runs at 90.2 images/s on an RTX 4090.
| Task | Benchmark | Metric | FoundYou |
|:--|:--|:--:|--:|
| Personalized segmentation | PerSeg | mIoU / bIoU | 96.4 / 85.6 |
| Personalized segmentation | PerMIS | mIoU / bIoU | 62.6 / 57.4 |
| Personalized retrieval | PerMIR | mAP | 92.1 |
| Personalized retrieval | ILIAS | mAP@1k | 32.5 |
## Citation
```bibtex
@inproceedings{trivigno2026foundyou,
title = {{FoundYou}: A Unified Model for Personalized Segmentation and Retrieval},
author = {Gabriele Trivigno and Marcos Alfaro and Claudia Cuttano and Gabriele Berton and Luis Pay{\'a} and Carlo Masone},
booktitle = {Computer Vision -- ECCV 2026},
pages = {585--604},
year = {2026},
publisher = {Springer Nature Switzerland},
address = {Cham},
doi = {10.1007/978-3-032-37041-9_31}
}
```
## License
Apache-2.0, like the [code](https://github.com/ga1i13o/FoundYou/blob/main/LICENSE). The SAM 2 weights that FoundYou builds on are also released under Apache-2.0 ([SAM 2 license](https://github.com/facebookresearch/sam2/blob/main/LICENSE)).
|